I wrote already about Adobe’s new implementation of Content Credentials and finally just got access to Firefly, their new image generation tool. Curiously, all you have to do to remove the content credentials is open the image(s) in Photoshop and resave them (making sure it’s still a JPG).
Poof!
No more content credentials.
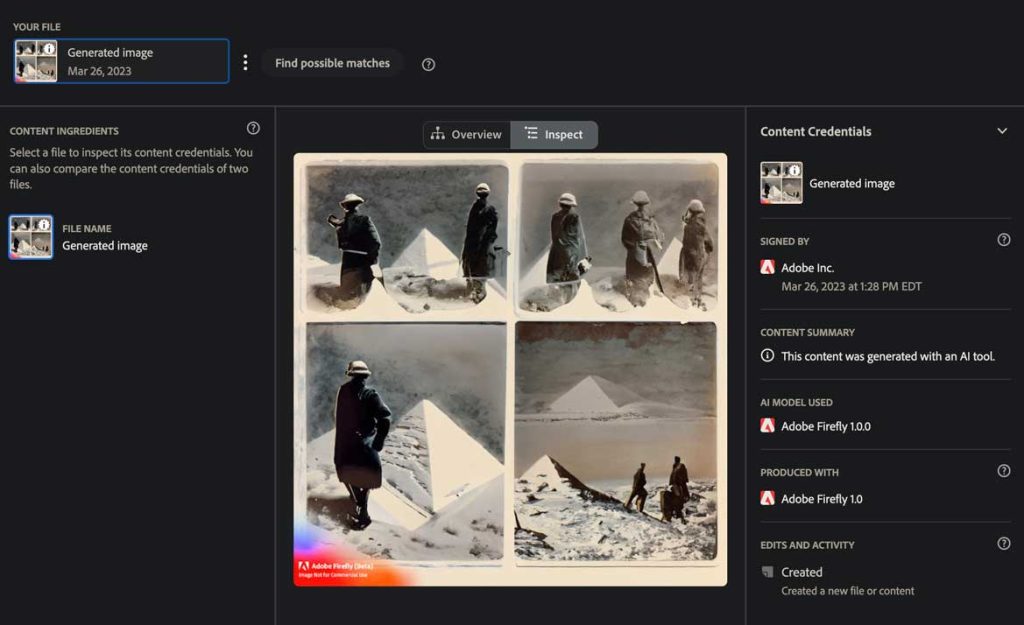
To test this out yourself, upload your original Firefly image here (this is Adobe’s tool). Then save your image in Photoshop & re-upload it. For your original uploads direct out of Firefly, you should see something like this:
In the sidebar, you see it says “Generated image” along the the date, AI model used, the signer (Adobe), and a summary that says “This content was generated with an AI tool.”
If you do that with the same file after saving it in Photoshop, you will instead get the message in the right sidebar:
No Content Credentials attached
There are no Content Credentials attached to this file.
Presumably the cause of this is I have Content Credentials turned off in Photoshop, which is resulting in not just a gap in the data, but the data being stripped out altogether. That seems a little weird, unless you don’t want this data attached to your files. Then this is good news, because it means it’s relatively easy to get rid of. You could write a macro or make a batch action or whatever to resave files in a folder, and you’re done.
Bonus: Remove watermark with content-aware fill
While you’re at it, if you don’t want that watermark to appear, the answer is quite easy. Just make a lasso around it, and then go to Edit > Content-aware fill.
Poof!
You’re done. It’s not always quite perfect (and feathering your selection edge might be in order), but it does a decent job. Now you can add that to your batch action to remove content credentials.
I know it’s early yet, but if both of these are so easy to remove, it’s worth making them optional, so users who don’t want them don’t have to jump through hoops for no real reason.
As for Twitter, he says it has brought out the worst in us. “It has a way of taking people who start out as distinct individuals and converging them into the same personality, optimised for Twitter engagement. That personality is insecure and nervous, focused on personal slights and affronted by claims of rights by others if they’re different people. The example I use is Trump, Kanye and Elon [Musk, who now owns Twitter]. Ten years ago they had distinct personalities. But they’ve converged to have a remarkable similarity of personality, and I think that’s the personality you get if you spend too much time on Twitter. It turns you into a little kid in a schoolyard who is both desperate for attention and afraid of being the one who gets beat up. You end up being this phoney who’s self-concerned but loses empathy for others.”
There’s a lot to unpack here, and I’ve tried a little to do so in some of my AI lore books, especially The Gestalt Minds and Inside Princeps. My versions veer off into sort of pulp sci fi explorations of some of those themes. It makes me think of a storyline, what if the purpose of apps was to make & regulate composite/collective human personalities, rather than sort of an accidental (maybe) byproduct of bad design choices?
Highly personalized AI would certainly be an ideal vector in a story like that, the gaslighting AI app that functions completely different for different people, but is slowly merging them into hyper-personalities…
Pretty good, though short & sort of unfocused article about Jaron Lanier’s hot take on AI causing mass insanity more so than killing us outright. Happen to agree with that & just wanted to capture this quote for future reference.
Lanier says the more sophisticated technology becomes, the more damage we can do with it, and the more we have a “responsibility to sanity”. In other words, a responsibility to act morally and humanely.
Adobe recently released V1 of its own suite of generative AI tools called “Firefly” (waitlist only for now – I don’t have access yet, but managed to piece together this information). Designed to integrate with Adobe’s existing apps, Firefly enables users to create generative AI images. Adobe has also incorporated “Content Credentials” into its AI-generated image outputs, asserting that the content was produced by AI (see the screenshot above).
Content Credentials are Adobe’s in-house implementation of the Coalition for Content Provenance and Authenticity (C2PA) standard. The C2PA is an open industry initiative focused on developing standards for tracing the provenance and authenticity of web media. By incorporating Content Credentials into Firefly, Adobe aims to promote transparency and trust in the AI-generated media space.
As part of the Content Authenticity Initiative (CAI) metadata, Adobe has introduced a custom assertion: com.adobe.generative-ai. This assertion helps establish that the content was generated using Adobe’s Firefly AI tools.
A new addition to the C2PA standard—digitalSourceType: trainedAlgorithmicMedia—will further complement Adobe’s efforts in the AI-generated media space. This new classification highlights the role of trained algorithms in generating media content, further establishing transparency.
Although social media platforms have yet to widely adopt the Content Credentials system, end users can verify content credentials of files on Adobe’s website at https://verify.contentauthenticity.org/ to see how the records work. This allows users to understand the provenance of AI-generated media and promotes transparency. You can also use Content Credentials currently in Photoshop.
Adobe has taken measures to ensure that the training data for its AI-generated images is curated from Adobe Stock and other reliable sources. According to the Firefly site, the curation process aims to mitigate harmful and biased content while respecting artists’ ownership and intellectual property rights (read more on CNET).
Here are two recent books I wrote using this app. It’s buggy, the software, but it works in a rough and tumble “good enough” kind of way for my purposes.
It elaborates on a story in one of the first four issues (I forget which, offhand) of the print paper The Algorithm, which ultimately was the genesis for these AI lore books (or one of them, anyway). In this world, there are huge mechanical trees which suck carbon out of the air more effectively than “real” trees. This one is based on actual projects people are undertaking even today IRL. The whole thing sounds so dystopian, it blows my mind!
And here’s the next book made with EncycGen, and a couple of other tools, including running those outputs back through GPT-4 for clean-up and normalization. This one is called Tales of Shelvin Parz.
Shelvin Parz today is but a little known ancient Quatrian magician, but in his time was one of the best known figures in all of that land. You can read a bit more about Shelvin Parz here.
The Shelvin Parz book marks a milestone in the AI lore book series: it is #75!
I’m loving the Bing image creator’s output quality (some people are claiming it uses the new Dall-E experimental update, but I have not yet confirmed that with a solid source).
Sadly the “boosts” system is a swing and a miss. Mainly because once you use your ten free generations, you can only get more by being forced to use Microsoft products (search, Edge, etc.). You have to earn 500 points in “Microsoft Rewards” to get five more boosts (which equal image generations, with 4 outputs per generation).
You. Can’t. Just. Buy. Credits.
Um, what? Look I’m an adult. I can just give you money for the service. I don’t want to jump through your stupid hoops & earn rewards for things I don’t care about. My “reward” as a user should simply be: I use the thing & the thing does what I asked &/or paid for.
Look, against my better judgement I actually did download and install Edge. And I found that shit to be even more annoying than expected (and I had low low expectations), and instantly uninstalled it. Only thing is, uninstallation was so complicated on a Mac that I had to download *ANOTHER* application just to thoroughly delete all that garbage.
And for whatever reason, I can’t even seem to use Bing Chat at all without using Edge. F that.
This is starting to feel less and less like Microsoft finally got with (or ahead of) the times, and more and more like they just want to cram me as a user into their pie-hole. I don’t like it. It feels gross and manipulative and dystopian, and like something ripped straight out of Conspiratopia.
If a creator uses a non-CAI-supported tool to edit a piece of content, or if they’re working in a CAI-supported tool without CAI capabilities turned on, then the data of any actions in those spaces won’t be captured. We will make sure to show when this data is missing. The CAI will keep promoting transparency and encouraging the use of CAI-supported editing workflows, but we ultimately believe that any CAI process should be explicitly opted into.
What if CAI data is stripped from an image?
Because CAI does not enforce digital rights management considerations around metadata, it’s possible for individuals or applications to strip CAI data from a file. If you inspect a file on the CAI Verify website and find that it has no Content Credentials, you may be able to find Content Credentials associated with the file on the Verify site by searching for possible matches.
In conversations around the use of labeling in synthetic or generative media (made with help from AI), sometimes the desirability of labeling in the first place seems like a foregone conclusion. I wonder if we can’t unpack that a little though, and by doing so maybe make the bigness of it all a little more comprehensible.
I won’t go so far as to say that I think it’s “solvable,” though. I think it’s just the new baseline condition we’re living in. And you don’t solve these kinds of conditions (not without dismantling many underlying structures, anyway) — you end up having to find a way to live with them.
It might actually be helpful to use that simple frame in the development of informal conventions and more formal standards: just giving us tools to live with the deluge. Rather than framing it as a thing we’re going to “solve” once and forever, or some kind of “fight” or conflict or whatever we have to win. Both of those lenses bring us towards more rigid conclusions about what is and isn’t possible, and end up hemming in our imaginations from possibly more fluid and less fragile conceptions that might end up being more easy to apply to real life.
So the questions I want to put on the table to start with are simple:
What is the desired effect of putting labels onto generative AI content? In other words, what do we believe it gets us?
What do we want the end user to do or not do as a result of the presence or absence of these labels?
How can we validate whether labeling actually drives: A) the user behavior we want, and B) that the user behavior will then have the desired effect?
Perhaps a related question would also be appropriate to examine from the beginning: how big of an impact can we realistically expect any labeling will have on users who are just fast-scrolling through news feeds all day?
Take for example this Verify tool view for a given image, as part of Adobe’s implementation of C2PA, the Content Authenticity Initiative:
I think the tool is well-intended, and there’s a lot of information being conveyed through this visualization of metadata.
But let’s make a conservative estimate that maybe the average web user encounters about 1,000 individual media artifacts in a giving day of scrolling, swiping, and browsing.
What’s the desired user behavior here? That each time a user encounters a piece of content, they should use an inspector to look up its provenance trail and then make some kind of rational determination based on the metadata that they find?
I think that pattern might appeal to a very narrow slice of users who have specific especially occupational needs related to information verification (like journalists), but for the average web user might be an undesirable extra set of steps. So I think it’s safe to say most people won’t do that, except in special cases. Which would mean, integrating metadata directly into the feed where people consume the content (as opposed to an external inspector like depicted above), and then hoping that it has the desired effect.
To speak more to that, I think sometimes the unexamined assumption in these conversations is that merely by being exposed to metadata about provenance, that people’s rational minds will be (rightly) persuaded to make appropriate reality-based decisions. It’s a noble idea, and it probably stems from Enlightenment era ideals about the superiority of Reason, etc. But it’s very much not how most people probably make most decisions, especially not on the internet.
We’ve been endlessly taught to “like” things online, or upvote things because we like them (or block them because we don’t like them). Not because they are inherently Good, or Right, or True. But because they align with our existing beliefs, notions, affiliations, identity, and feelings.
Where then does a rationally-intended datum about origin belong in all of that? It’s less clear than it seems at first glance… though there is a school of thought that says we should always make available more contextual data wherever we can. In which provenance becomes just one of many dimensions of contextual data (perhaps not unlike the Four Corners Initiative). Looking from that broader picture into this problem space might open up new vistas of what’s possible and desirable.
Going back to question 2 above: if the end user behavior we want is actually that users slow down when consuming information (as I touched on here), and consider things more carefully, examine metadata, and make rational decisions, well, then we need to redesign social media and the modern web altogether. Putting another sticker on top of the mechanistic beast that drives us directly in the opposite direction by design, is – in my humble opinion – not going to have the desired effect.
If what we want is actually more like “slow media,” and careful considered consumption, then let’s rebuild everything underneath these labels. Let’s change the core technology that brought us here in the first place. Otherwise, there’s a decent chance we will run around chasing our tails and wondering why things aren’t working as intended.
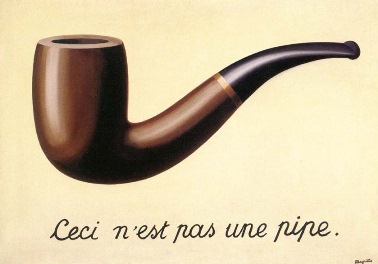
At a call today on deepfakes & content labeling, this famous image from Magritte came to mind after someone showed a deepfake video with an opening disclaimer about how the events in it did not really happen:
In English, this painting is called the Treachery of Images, and the French words on it translate to “this is not a pipe.”
Wikipedia attributes this quote to Magritte about it:
The famous pipe. How people reproached me for it! And yet, could you stuff my pipe? No, it’s just a representation, is it not? So if I had written on my picture “This is a pipe”, I’d have been lying!
— René Magritte
Part of what this brings to mind for me is that, apart from real life itself, literally all media artifacts are representations. They are not the “thing itself” but a representation of the thing.
But as Magritte cunningly points out, is a photo of a painting (a representation of a representation) actually “real life?” For sure, we know (well, we trust – we take it on good authority) that the original physical painting exists somewhere (the LA County Art Museum, apparently).
But where does the “real life” start and stop in this meta-situation? Is this painting a “deepfake?” (I hate that label) Is it an example of a labeling success or a failure?
It’s funny yesterday I was looking around for videos about coding with ChatGPT from a “no code” perspective (or rather for people who don’t already know how to code – no know code?), and it was funny to me that two month old videos on the topic are already hopelessly out of date. Seeing those, it’s like thanks for the tips grandpa.
Also of note in that pile of search results is in casual skimming, it seemed like almost every one of the videos I watched was by somebody who already has somewhat advanced knowledge of coding/programming/engineering/computer science. There was no one I could relate to from my now decades old base of antiquated hand-crafted HTML & CSS knowledge.
The single thing I probably find the most frustrating in the coding with ChatGPT experience is actually not the errors or small harmless mistakes it makes. It is instead its habit of accidentally removing blocks of your code when it spits back out “corrected” versions of things.
If you’re chasing down a solution to a (different) specific bug, it might go unnoticed by you for some time that a couple of buttons have been removed. By then the content of your functions may have been changed, and references to them removed. Then you have to (gently) berate the model until it brings back the functionality you had before that was working perfectly fine but was removed for some inexplicable reason… The circle goes round and round.
I’m not sure how to correct for that, but it’s a major issue for my current learning process….
Integrated coding assistant
Through this experience, I’ve started to visualize in my mind’s image diffusion model what it might look like, how it might function, to have a chat assistant integrated into a coding program/development environment. I’m not that up to date on all the preferred terminology and technology and methods in all this stuff. In a way, that’s what’s appealing to me about using ChatGPT as a non-coder to code different creative production utilities: I don’t have to be. If I want to learn about any specific aspect of it, I can drill down on a problem, ask the model questions, etc. But I don’t have to know how it all works, just know that it works. As I gain experience working with it, anyway, I know the rest will come.
So what would a coding app with a chat assistant look like? I figure, broadly, a pane on the left with the chat conversation, and a pane on the right with the code. I tried getting ChatGPT to build it already, but it looks like it will take a little leg work. I’m up for it now though. I don’t know how it all works, but unlike before with “pure” coding, I never felt like it was possible to break through all the bazillions of road blocks to doing the thing I wanted to do. And hence it stunted my ability to visualize in that direction. But now, I know if I plod along, and am patient with all the errors and code drops, I can probably kinda sorta get there in a relatively short time. A few days of tinkering – but the fun kind of tinkering, not the horrible torturous kind.
Functionally, you could describe in chat what you want to build and how it should look & work. It would render the code right into the code pane, with comments & a chat explanation. You could manipulate the code yourself directly, or ask it to change in chat. It would highlight what it is changing & why, ask for permission, and keep prior versions. It could also optionally offer suggestions for improvements or warnings if it looks like your code might have an error.
The chat assistant, to make it more explicit, would always have access to an up to date version of your code, so you’re not constantly having to cut and paste back and forth. And it’s not making suggestions to you based on code that’s now out of date. I think this is part of the cause of (some of) the code bits getting dropped in transition.
Anyway, then you could preview the code in a browser, and the chat assistant would also have access to your error messages without having to copy paste those back and forth too. Really, all the copy pasting is the most annoying bit of how it all works with them as separate tools right now.
An advanced version might also let me select items in the preview, and say “make this work like this” in chat, and then code would be updated to reflect that.
It sounds like a big project with a lot of moving parts for a total novice, but I might at least try to carve off parts of it until someone else can do it better. It seems like a no brainer set of tools to have!